
The Cost of Context Window Bloat
Modern foundation language models offer massive context windows (ranging from 128,000 to over 1,000,000 tokens). While expansive context windows simplify prototyping by allowing engineers to dump entire documents or database schemas into prompts, they introduce significant production liabilities: linear increases in token latency (Time-to-First-Token) and quadratic cost scaling at enterprise throughput.
Python AST Schema Compaction Algorithm
When sending database schemas or JSON objects to an LLM for SQL or code generation, standard formatting contains excessive whitespace, redundant field comments, and unnecessary metadata. The following Python function parses raw JSON schemas, removes empty keys, truncates null objects, and compresses whitespace without altering semantic meaning:
import json
import re

def compress_context_schema(schema_dict: dict) -> str:
    """
    Minimizes JSON context payloads by stripping null values,
    unnecessary descriptive metadata, and redundant whitespace.
    """
    def clean_obj(obj):
        if isinstance(obj, dict):
            # Retain only essential schema attributes (name, type, foreign keys)
            essential = {"name", "type", "description", "required", "properties", "items"}
            cleaned = {
                k: clean_obj(v) for k, v in obj.items()
                if v is not None and v != "" and (k in essential or not k.startswith("$"))
            }
            return {k: v for k, v in cleaned.items() if v != {}}
        elif isinstance(obj, list):
            return [clean_obj(item) for item in obj if item is not None]
        return obj

    cleaned = clean_obj(schema_dict)
    compact_json = json.dumps(cleaned, separators=(",", ":"))
    # Normalize double spaces and escaped line returns
    return re.sub(r'\s+', ' ', compact_json).strip()
Empirical Latency and Cost Impact
Compacting input payloads produces measurable improvements in production workloads:
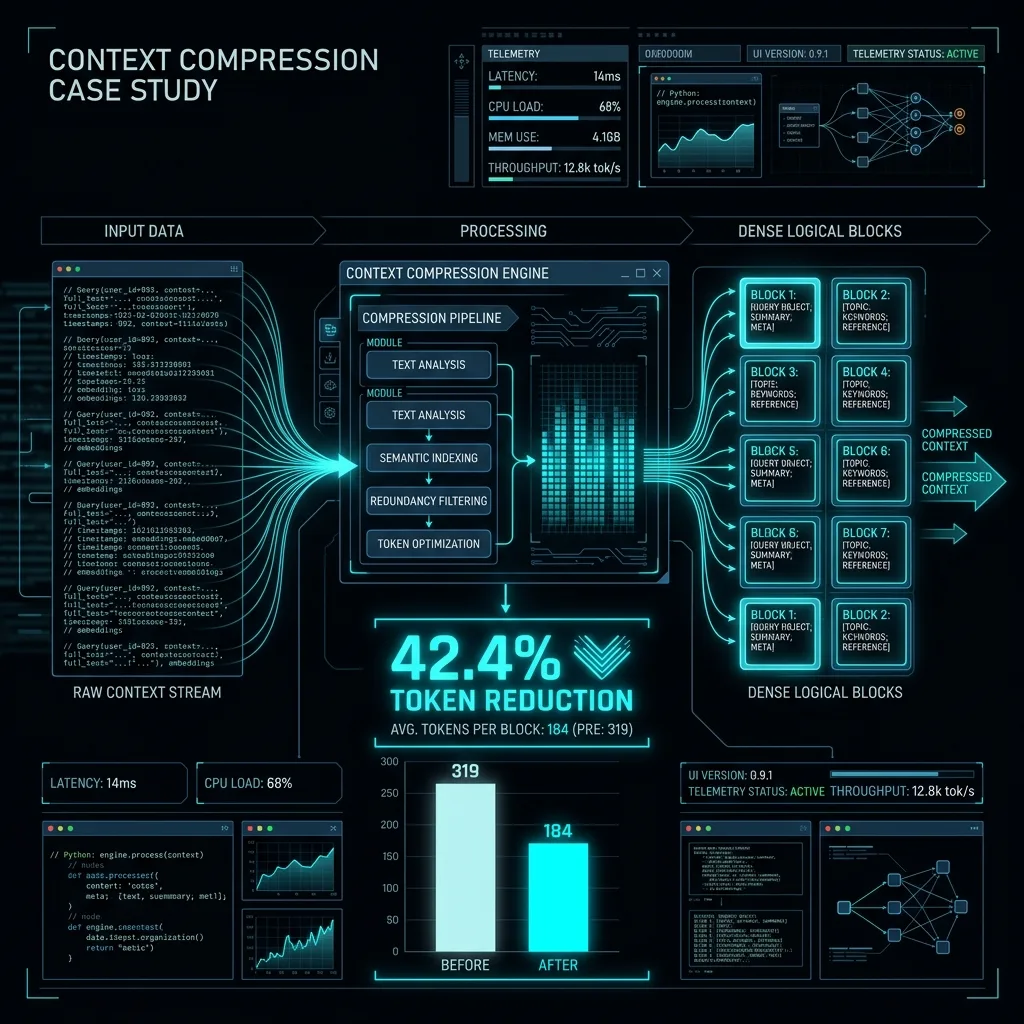
- Payload token count reduced by 30% to 50% across complex multi-table schemas.
- Average API response latency drops by 200ms to 450ms per request.
- Cumulative API billing decreases proportionally with input token reduction.