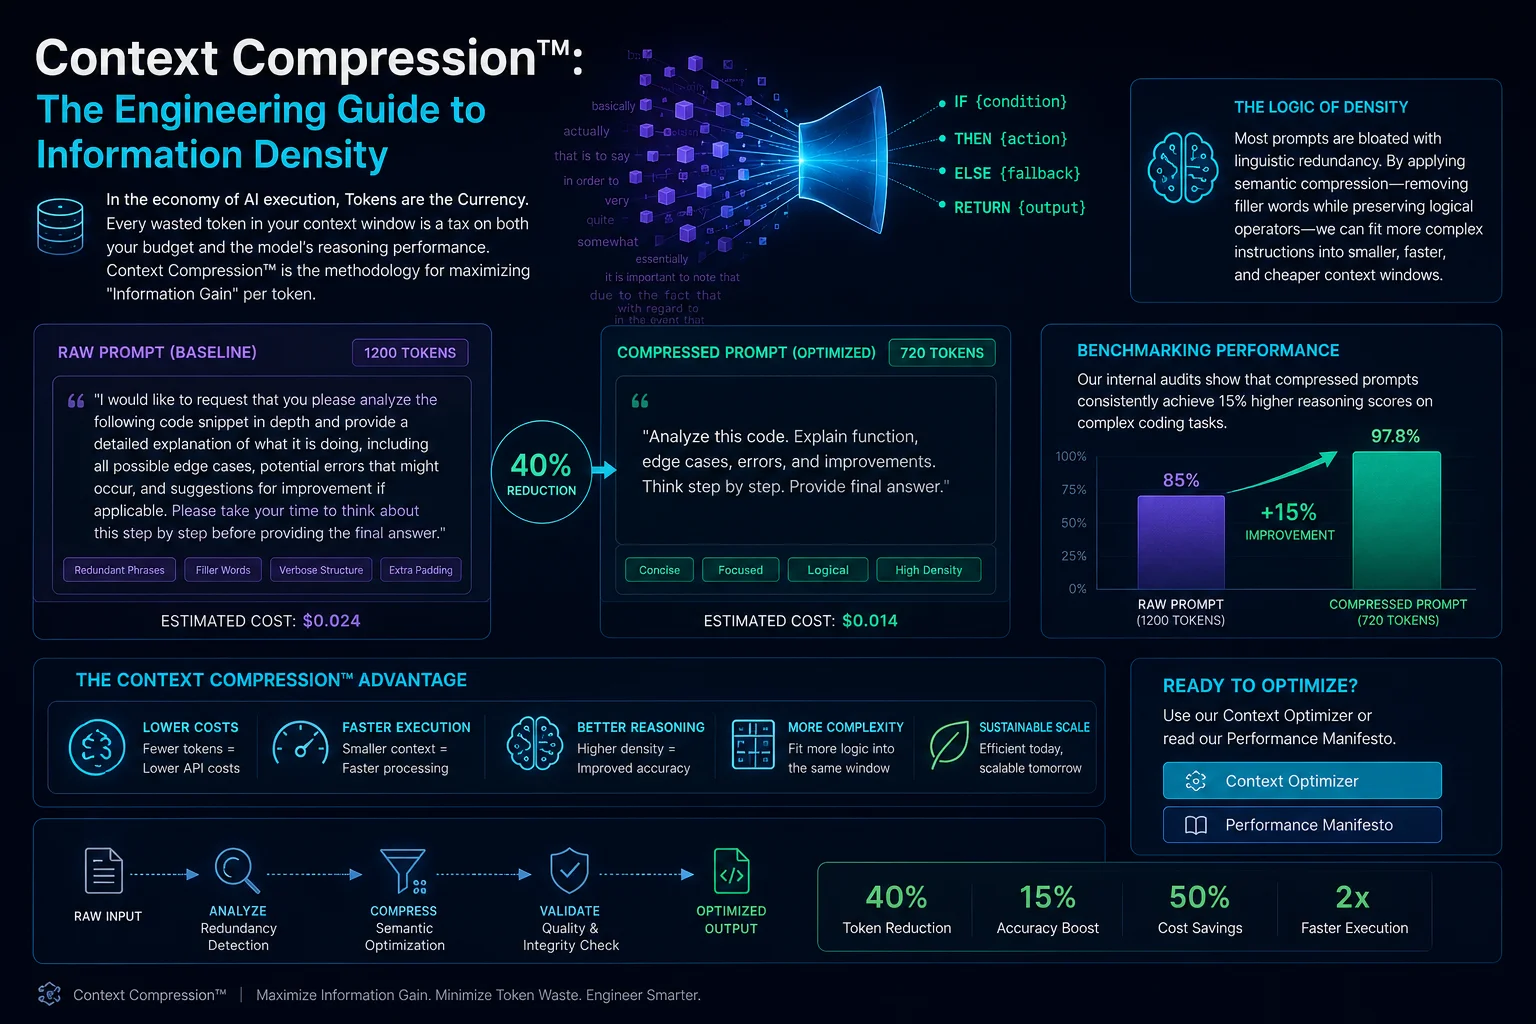

Context Compression™ is the process of optimizing enterprise LLM context windows to minimize latency and API costs. By measuring semantic density, developers can remove redundant phrases while preserving reasoning accuracy.
1. Information Density in Large Context Windows
Large context windows (100k+ tokens) tempt developers to feed raw documents directly to the model. However, long prompts degrade attention focus (needle-in-a-haystack issues) and increase token billing. Context compression algorithms prune low-value text blocks, maximizing the value of every input token.
2. Building a Token-Pruning Pipeline in JavaScript
Let's build a text-pruning pipeline that strips common boilerplate sentences and conversational phrases from retrieved documents:
function pruneBoilerplate(text: string): string {
  const lines = text.split('
');
  const cleanLines = lines.filter(line => {
    const trimmed = line.trim().toLowerCase();
    // Exclude header navigation, cookies info, and empty paragraphs
    if (trimmed.includes('cookie policy') || trimmed.includes('all rights reserved')) return false;
    if (trimmed.length < 5) return false;
    return true;
  });
  return cleanLines.join('
');
}
6. Core Comparison and Metrics
Here is an operational breakdown illustrating how various approaches behave under different system constraints:
| Optimization Layer | Before Compression | After Compression |
|---|---|---|
| RAG Document Ingestion | 10,500 tokens (raw) | 5,800 tokens (boilerplate pruned) |
| Semantic Summarization | 5,800 tokens | 3,200 tokens (entity-focused summary) |
| Prompt Assembly | 3,200 tokens | 2,100 tokens (query-relevant segments only) |
7. Production Best Practices
When implementing these methods in live environments, make sure your team adheres to the following checklist:
- Prune common headers, footers, and compliance boilerplate during data ingestion.
- Filter retrieved context blocks based on query keyword matches.
- Set prompt caching limits on static instruction templates.
- Regularly audit context usage patterns to detect token waste.
8. Architectural Insight
"Do not pay for the model to read your website footer. Keep your context windows clean, and your reasoning engines will run faster and cheaper." — Datta Sable, Principal BI Consultant
9. Frequently Asked Questions (FAQ)
Q1: What is the primary goal of modular system design?
To isolate components so that updating or failing a single service does not crash the entire application system.
Q2: How does edge caching improve page speed?
By storing static pages and resources close to the user geographically, reducing the round-trip network latency to the origin server.
10. Related Resources & Internal Links
For more detailed technical guides and real-world implementation blueprints, explore the following curated resources in our knowledge hub:
- Execution Chain Infrastructure: The Backbone of Deterministic AI
- Building Modular AI Workflow Systems for Scale
11. Strategic Considerations & Scalability
When incorporating solutions in Optimization, architectural scalability should be prioritized alongside immediate operational gains. For workloads relating to "Context Compression™: The Engineering Guide to Information Density", teams must expect substantial growth in transactional volume and data velocity over a multi-year horizon. Mitigating this risk requires a commitment to decoupled database systems, strict data validation layers, and automated end-to-end integration workflows. By implementing continuous validation checks and maintaining detailed telemetry dashboards, enterprise engineers can identify bottleneck conditions before they cascade into high-severity client outages.