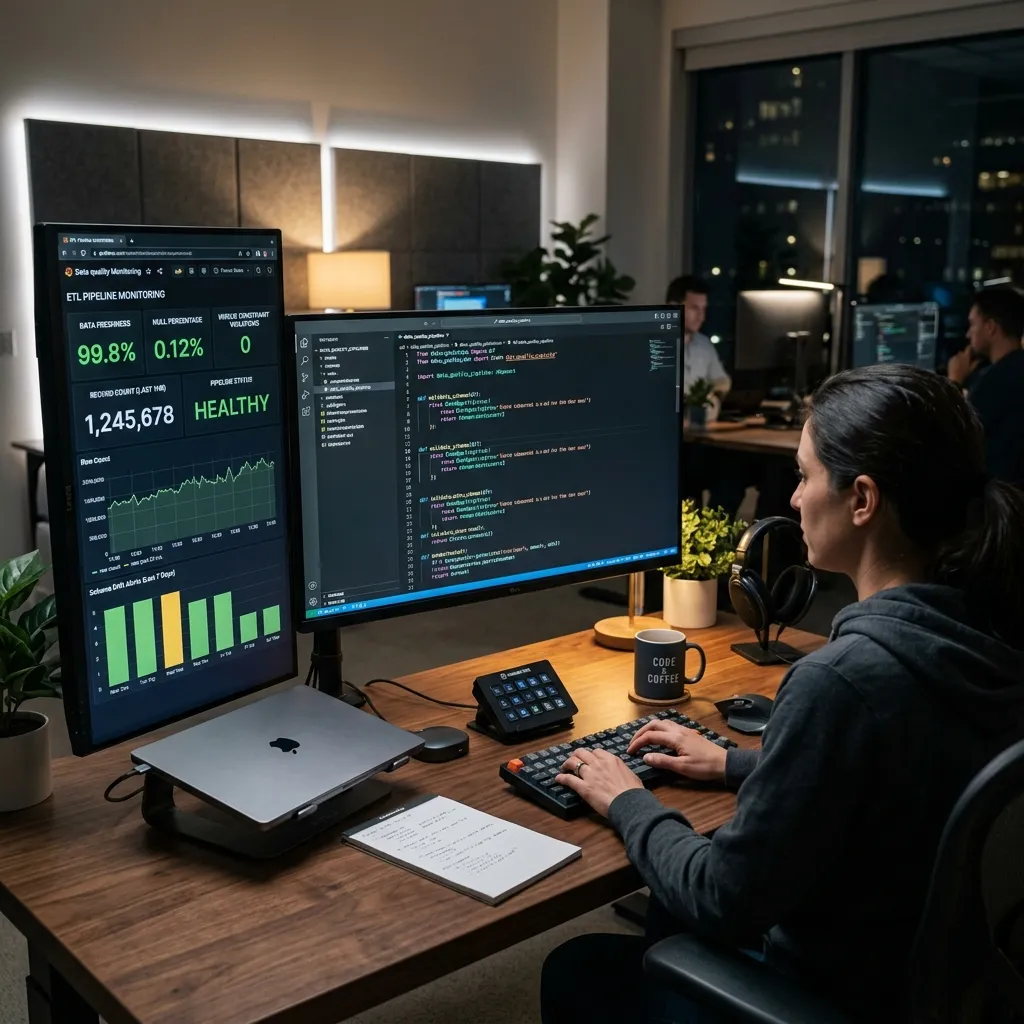

Data Quality is the foundation of corporate trust. This guide details how to build a zero-trust validation framework that intercepts bad data before it reaches executive dashboards.
1. Implementing Automated Data Quality Audits
Stale data or missing columns in pipelines lead to inaccurate business decisions. A zero-trust data pipeline treats incoming data as untrusted. We run automated checks (null checks, range validations, schema checks) at every stage of the ETL pipeline to isolate anomalies immediately.
2. Setting Up an Ingestion Schema Validation in Python
Below is a Python validation function that intercepts anomalous transaction logs before writing to the database:
def validate_transaction_log(row: dict) -> bool:
    required_keys = ['tx_id', 'amount', 'timestamp']
    # Check key presence
    if not all(k in row for k in required_keys):
        return False
    # Validate value ranges
    if row['amount'] <= 0 or row['amount'] > 1000000:
        return False
    return True
6. Core Comparison and Metrics
Here is an operational breakdown illustrating how various approaches behave under different system constraints:
| Pipeline Stage | Legacy Validation | Zero-Trust Data Quality |
|---|---|---|
| Data Ingestion | Ingests raw records directly | Intercepts and validates rows against JSON schemas |
| Schema Drift Handling | Crashes SQL queries downstream | Quarantines anomalous rows and alerts developers |
| Data Freshness Audits | Manual weekly checks | Automated rolling freshness alerts |
7. Production Best Practices
When implementing these methods in live environments, make sure your team adheres to the following checklist:
- Define strict validation schemas for all external data sources.
- Quarantine anomalous records instead of crashing the entire pipeline.
- Monitor data freshness metrics and set alert triggers for stale tables.
- Include data quality scores directly on executive dashboard cards.
8. Architectural Insight
"Publishing reports containing unchecked data is a major liability. Build validation gates into your pipelines, and guarantee data trust." — Datta Sable, Principal BI Consultant
9. Frequently Asked Questions (FAQ)
Q1: What is the primary goal of modular system design?
To isolate components so that updating or failing a single service does not crash the entire application system.
Q2: How does edge caching improve page speed?
By storing static pages and resources close to the user geographically, reducing the round-trip network latency to the origin server.
10. Related Resources & Internal Links
For more detailed technical guides and real-world implementation blueprints, explore the following curated resources in our knowledge hub:
- Execution Chain Infrastructure: The Backbone of Deterministic AI
- Engineering the Sentinel: Architecting a 10M-Record Fraud Detection System
11. Strategic Considerations & Scalability
When incorporating solutions in Engineering, architectural scalability should be prioritized alongside immediate operational gains. For workloads relating to "Building a ", teams must expect substantial growth in transactional volume and data velocity over a multi-year horizon. Mitigating this risk requires a commitment to decoupled database systems, strict data validation layers, and automated end-to-end integration workflows. By implementing continuous validation checks and maintaining detailed telemetry dashboards, enterprise engineers can identify bottleneck conditions before they cascade into high-severity client outages.