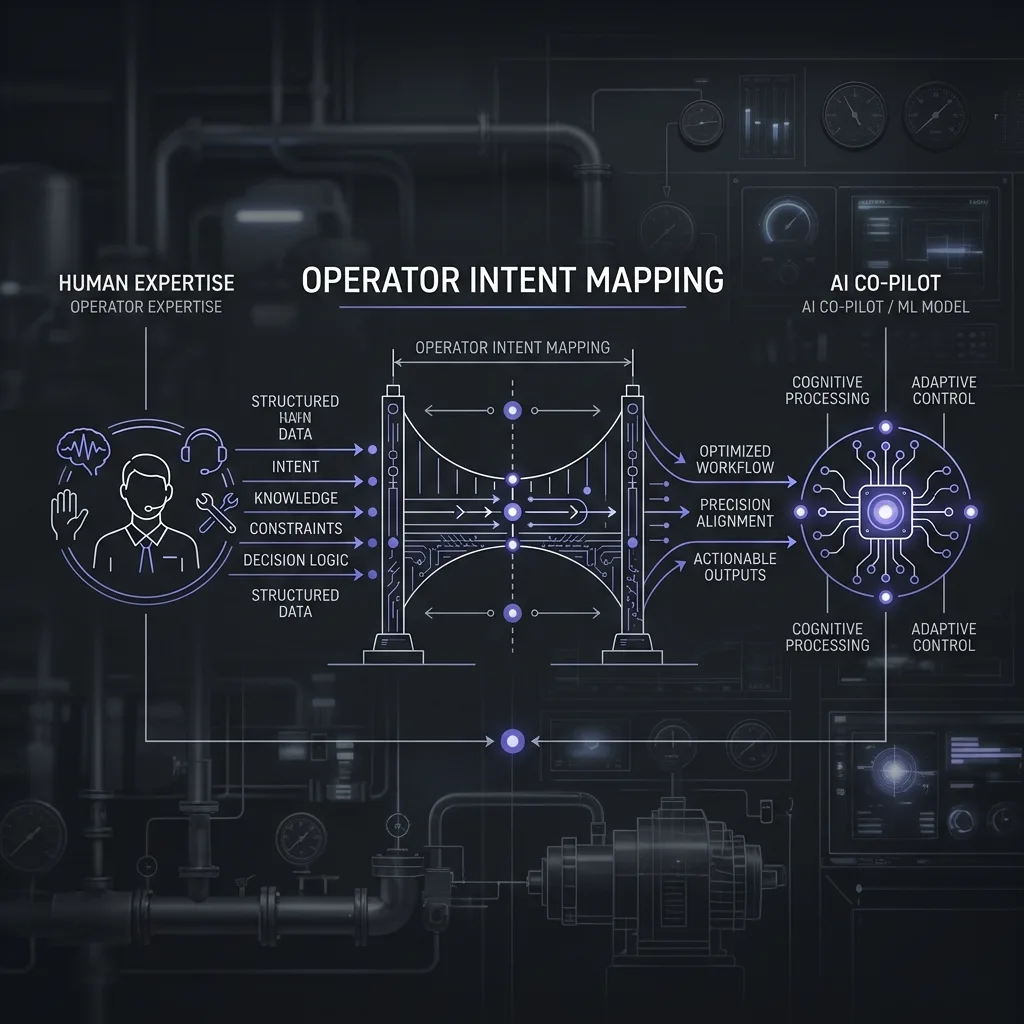

Operator Intent Mapping™ is a system architecture designed to align AI actions with human intent. By analyzing queries and routing them to specialized execution paths, it prevents model drift and ensures predictable agency.
1. Aligning Queries with Specialized AI Workflows
A common issue in AI systems is using a single LLM call to handle every user request. This 'one-size-fits-all' approach leads to slow speeds, high costs, and incorrect answers. Intent Mapping acts as a router, classifying user queries into specific 'intents' and passing them to optimized, specialized execution routines.
2. Implementing an Intent Routing Node in Python
Let's build a classification node that analyzes input text and returns a structured intent string using typed enumeration routing:
from enum import Enum
from typing import TypedDict

class UserIntent(str, Enum):
    ANALYTICS = "analytics"
    DATA_EXPORT = "data_export"
    GENERAL = "general"

class ClassificationResult(TypedDict):
    query: str
    intent: UserIntent
    confidence: float

def route_query(query: str) -> UserIntent:
    # Basic matching logic (can be replaced with LLM/Embeddings classifier)
    q = query.lower()
    if "report" in q or "chart" in q or "sales" in q:
        return UserIntent.ANALYTICS
    elif "download" in q or "csv" in q or "export" in q:
        return UserIntent.DATA_EXPORT
    return UserIntent.GENERAL
6. Core Comparison and Metrics
Here is an operational breakdown illustrating how various approaches behave under different system constraints:
| Aspect | Unstructured AI Processing | Intent Mapping Routing |
|---|---|---|
| Execution Latency | High (complex prompt processed) | Low (queries routed to specific tasks) |
| Accuracy | Variable (model handles too many tasks) | High (focused prompts handle single tasks) |
| Cost | Expensive (large global system prompts) | Optimized (minimal tokens sent to specialized nodes) |
7. Production Best Practices
When implementing these methods in live environments, make sure your team adheres to the following checklist:
- Keep intent categories distinct and mutually exclusive.
- Build a lightweight classifier (regex or small model) before calling heavy LLMs.
- Include a fallback path for unrecognized or ambiguous intents.
- Log misclassified queries to iteratively refine classification keywords.
8. Architectural Insight
"An intelligent agent is only as good as its routing layer. Before resolving a request, you must accurately understand exactly what task the user is trying to accomplish." — Datta Sable, Principal BI Consultant
9. Frequently Asked Questions (FAQ)
Q1: What is the primary goal of modular system design?
To isolate components so that updating or failing a single service does not crash the entire application system.
Q2: How does edge caching improve page speed?
By storing static pages and resources close to the user geographically, reducing the round-trip network latency to the origin server.
10. Related Resources & Internal Links
For more detailed technical guides and real-world implementation blueprints, explore the following curated resources in our knowledge hub:
- Building Modular AI Workflow Systems for Scale
- Execution Chain Infrastructure: The Backbone of Deterministic AI
11. Strategic Considerations & Scalability
When incorporating solutions in Workflow, architectural scalability should be prioritized alongside immediate operational gains. For workloads relating to "Operator Intent Mapping™: Aligning AI Systems with Human Persona", teams must expect substantial growth in transactional volume and data velocity over a multi-year horizon. Mitigating this risk requires a commitment to decoupled database systems, strict data validation layers, and automated end-to-end integration workflows. By implementing continuous validation checks and maintaining detailed telemetry dashboards, enterprise engineers can identify bottleneck conditions before they cascade into high-severity client outages.